Authors examine the effectiveness of Large Language Models (LLMs) like BERT, MathBERT, and OpenAI GPT-3.5 in assisting middle school students with math word problems, particularly following the decline in math performance post-COVID-19.
Read More...Assessing large language models for math tutoring effectiveness
Authors examine the effectiveness of Large Language Models (LLMs) like BERT, MathBERT, and OpenAI GPT-3.5 in assisting middle school students with math word problems, particularly following the decline in math performance post-COVID-19.
Read More...Large Language Models are Good Translators
Machine translation remains a challenging area in artificial intelligence, with neural machine translation (NMT) making significant strides over the past decade but still facing hurdles, particularly in translation quality due to the reliance on expensive bilingual training data. This study explores whether large language models (LLMs), like GPT-4, can be effectively adapted for translation tasks and outperform traditional NMT systems.
Read More...Comparison of three large language models as middle school math tutoring assistants
Middle school math forms the basis for advanced mathematical courses leading up to the university level. Large language models (LLMs) have the potential to power next-generation educational technologies, acting as digital tutors to students. The main objective of this study was to determine whether LLMs like ChatGPT, Bard, and Llama 2 can serve as reliable middle school math tutoring assistants on three tutoring tasks: hint generation, comprehensive solution, and exercise creation.
Read More...Validating DTAPs with large language models: A novel approach to drug repurposing
Here, the authors investigated the integration of large language models (LLMs) with drug target affinity predictors (DTAPs) to improve drug repurposing, demonstrating a significant increase in prediction accuracy, particularly with GPT-4, for psychotropic drugs and the sigma-1 receptor. This novel approach offers to potentially accelerate and reduce the cost of drug discovery by efficiently identifying new therapeutic uses for existing drugs.
Read More...Training and comparison of fine-tuned small language models as math tutoring assistants
Here the authors evaluateE various configurations of Llama 3.2 models (ranging from 1B to 8B parameters trained across 1 to 5 epochs) to serve as cost-effective math tutoring assistants for K-12 classrooms. Their findings show that while the largest 8B model trained for 5 epochs achieved peak accuracy, smaller fine-tuned models provide a viable, resource-efficient balance for practical educational deployment.
Read More...Using text embedding models as text classifiers with medical data
This article describes the classification of medical text data using vector databases and text embedding. Various large language models were used to generate this medical data for the classification task.
Read More...An explainable AI framework for studying query complexity and hallucinations in LLM scheduling tasks
In this study, we investigated how the complexity of a query can influence tool-use hallucinations in large language models that were tasked with setting an appointment. Using explainable AI (XAI) as a tool to test the hypothesis, we analyzed trends in hallucination rates by the type of query and saw results that when complexity and ambiguity of the query increased (such as asking for multiple days or unclear time ranges), the model was more likely to make errors due to misunderstanding time-related data from tool outputs. This shows that making large language models (LLMs) understand what seems logical to a human is still difficult, especially in complex tasks, and that knowing what causes these errors can help build more trustworthy AI systems.
Read More...Evaluating the impact of prompting styles on LLM accuracy for AIME math questions
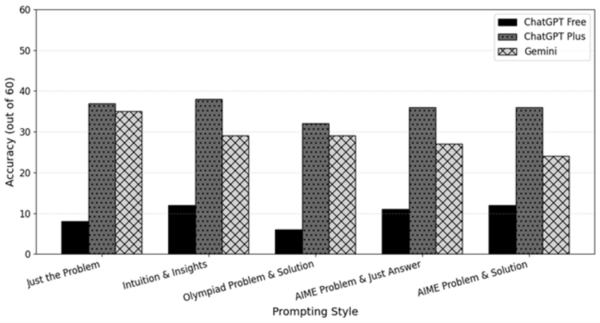
Large language models are increasingly used to solve math problems, but their ability to handle multi-step reasoning remains uncertain. In this study, students tested whether different prompting styles could improve LLM accuracy on challenging AIME math questions and found that detailed step-by-step solutions did not significantly outperform simpler prompts. These results suggest that improving LLM mathematical reasoning may require deeper model-level advances rather than changes in prompting style alone.
Read More...A natural language processing approach to skill identification in the job market
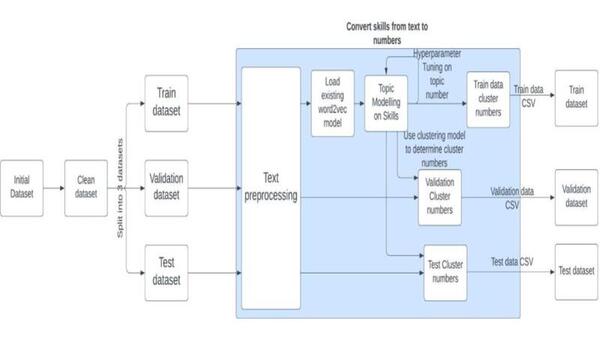
The authors looked at using machine learning to identify skills needed to apply for certain jobs, specifically looking at different techniques to parse apart the text. They found that Bidirectional Encoder Representation of Transforms (BERT) performed best.
Read More...Comparing and evaluating ChatGPT’s performance giving financial advice with Reddit questions and answers
Here, the authors compared financial advice output by chat-GPT to actual Reddit comments from the "r/Financial Planning" subreddit. By assessing the model's response content, length, and advice they found that while artificial intelligence can deliver information, it failed in its delivery, clarity, and decisiveness.
Read More...